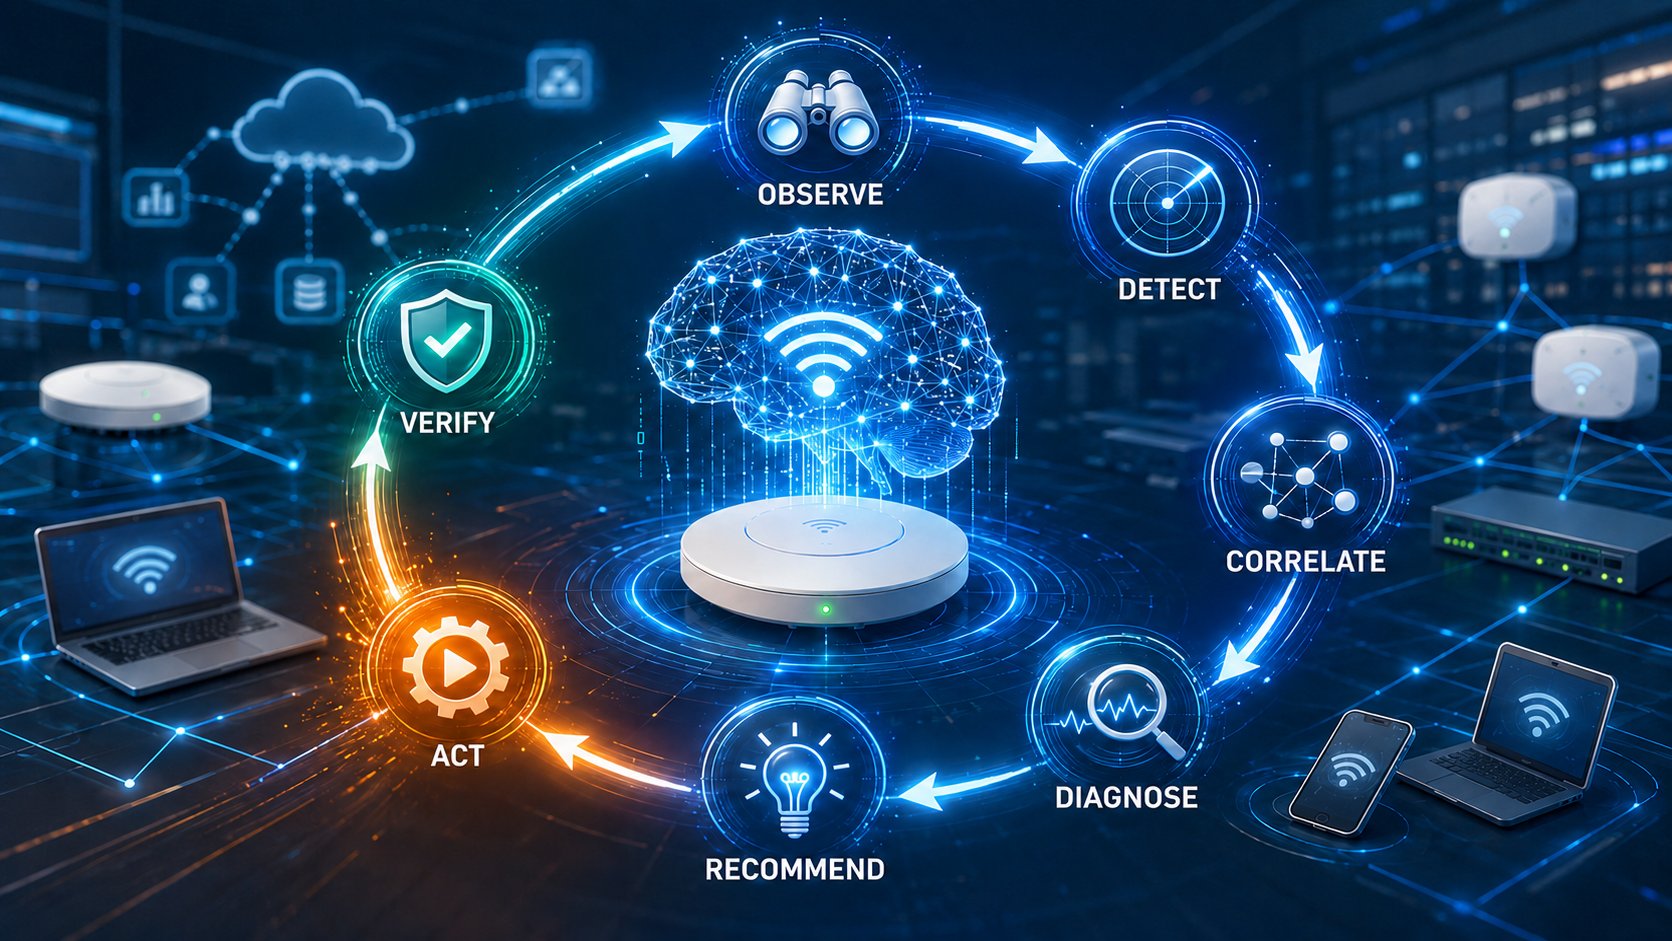

Collecting network data is only the beginning. The real value of AI Operations emerges when platforms can identify problems, determine their likely causes, recommend corrective action, and – in carefully controlled cases – resolve issues automatically.
In Part One of this series, we examined what AI Operations means for enterprise Wi‑Fi. Part Two explored the data foundation required to make AI useful. Now we turn to the operational process itself: How does an AI Ops platform transform millions of network observations into actions that improve Wi‑Fi performance? The answer is best understood as a progression from visibility to autonomy.
Beyond dashboards and alarms
Traditional network management systems are good at reporting events. They can show that an access point is down, a client has a weak signal, or a channel has become congested. The problem is that enterprise networks generate enormous numbers of events – and not every event represents a problem. A sudden increase in retransmissions might indicate interference, poor coverage, a badly behaving client, or simply a temporary change in traffic. Multiple alarms may also be different symptoms of the same underlying issue. This leaves network teams with three difficult questions:
- Which events are important?
- What is actually causing them?
- What should be done about them?
AI Ops is intended to answer these questions by analysing events in context rather than treating each one as an isolated alarm.
Step one: Establish what normal looks like
Static thresholds are a blunt instrument. A utilisation level that is perfectly normal in a conference centre during an event might indicate a serious problem in a small branch office. AI Ops platforms can instead establish baselines for individual sites, access points, client types, applications, and periods of the day. The system can then detect deviations from the behaviour normally associated with that environment.
This does not necessarily require generative AI. Statistical models and machine learning have been used for years to identify anomalies, classify problems, and recognise recurring patterns. The important shift is from asking whether a metric has crossed a fixed threshold to asking whether the network is behaving abnormally—and whether the change is affecting users.
Step two: Correlate symptoms across the network
Wi‑Fi problems rarely exist entirely within the radio network. A user may report that “the Wi‑Fi is slow,” while the real cause is a failed DHCP transaction, a slow DNS response, an authentication problem, a congested WAN connection, or an application server located hundreds of kilometres away.
An effective AI Ops platform therefore needs visibility beyond access points and RF conditions. It must be able to correlate information from clients, access points, switches, authentication systems, DHCP and DNS services, WAN links, applications, and other parts of the infrastructure. This correlation is what allows the platform to distinguish between a Wi‑Fi symptom and a Wi‑Fi cause.
It can also consolidate hundreds of related alerts into a single incident. Instead of reporting that 40 access points and 600 clients are experiencing problems, the platform might identify one failing upstream switch or one authentication service as the probable common cause.
Step three: Identify the likely root cause
Root-cause analysis is among the most valuable – and most difficult – functions of AI Ops. The platform must examine sequences of events, dependencies between network components, historical patterns, configuration changes, and previous incidents. It may then rank several possible causes according to probability. For example, poor application performance could be associated with:
- Excessive RF interference
- Insufficient capacity
- Poor client roaming
- Authentication delays
- DHCP or DNS failures
- Incorrect switch configuration
- WAN congestion
- A problem with the application itself
The quality of this analysis depends heavily on the scope and quality of the available data. If the platform sees only the wireless layer, it may be unable to determine whether a problem originated elsewhere. AI should therefore not be judged simply by whether it produces an answer. The important question is whether the answer is supported by sufficient evidence and presented with enough context for the operator to trust it.
Step four: Prioritise according to user impact
Not every anomaly needs immediate attention. An access point briefly changing channels at an empty site may be operationally irrelevant. A small increase in authentication failures at a hospital or warehouse could be critical. AI Ops platforms can help prioritise incidents according to their effect on users, devices, applications, sites, and business services. This is a significant improvement over traditional alarm systems, which often treat infrastructure events as equally important regardless of their consequences. The most useful platforms increasingly focus on service levels and user experience rather than device status alone. They attempt to answer questions such as:
- How many users are affected?
- Which applications or services are being disrupted?
- Is the problem isolated or widespread?
- Is performance deteriorating?
- Does the incident require immediate intervention?
This helps network teams direct their attention towards the problems that matter most.
Step five: Recommend corrective action
Once a likely cause has been identified, the system can propose a solution. This might involve changing a configuration, adjusting radio parameters, upgrading firmware, restarting a port, isolating a rogue device, or opening a support case with the relevant diagnostic information already attached. At this stage, AI acts as an assistant. The platform investigates the incident and recommends an action, but a human operator decides whether that action should be executed.
This approach can substantially reduce troubleshooting time while preserving human control. It is particularly valuable when the system explains why it reached its conclusion, identifies the evidence supporting it, and predicts the likely effect of the proposed change.
Step six: Automate within defined guardrails
The final step is closed-loop automation: The platform detects a problem, determines the cause, executes a corrective action, and verifies whether the action worked. Some enterprise networking platforms already support bounded forms of this model. Examples include automatically adjusting channels or channel widths, correcting configuration or firmware non-compliance, disabling a port connected to a rogue DHCP server, or restarting a malfunctioning port.
The word bounded is important. Fully autonomous operation across an entire enterprise network remains a much more ambitious proposition. Different actions carry different levels of risk. Changing an RF parameter may be relatively safe and easily reversed. Modifying security policy, disabling infrastructure, or upgrading large numbers of access points could have much greater consequences. Enterprises will therefore need explicit operational guardrails, including:
- Defined permissions for each type of action
- Site- or device-specific policies
- Maintenance windows
- Limits on the number of affected devices
- Automatic rollback where possible
- Complete audit trails
- Post-action validation
- Escalation when automation fails
Trust will be earned incrementally. Most organisations are likely to begin with recommendations, progress to operator-approved actions, and permit full automation only for well-understood and low-risk procedures.
Generative and agentic AI change the interface
Generative AI adds a more intuitive way for administrators to interact with network intelligence. Instead of navigating multiple dashboards, an operator can ask why users at a particular site experienced poor connectivity and request the supporting evidence. Agentic AI goes further by allowing software agents to investigate incidents, coordinate workflows, interact with external systems, and potentially execute actions within defined policies.
These technologies may dramatically simplify operations, but they do not replace the underlying analytics. A conversational interface is useful only when it has access to accurate telemetry, reliable domain models, historical context, and trustworthy automation. A fluent answer is not the same as a correct diagnosis.
The objective is a verified operational loop
The most advanced AI Ops model is not simply detect and act. Instead it is this: Observe, detect, correlate, diagnose, recommend, act, and verify. Verification closes the loop. After changing the network, the platform must determine whether the original problem has disappeared, whether user experience has improved, and whether the action created any unintended consequences.
If the problem persists, the system should reopen the incident, reassess its diagnosis, or escalate the case to a human operator. This ability to evaluate outcomes may ultimately become one of the most important differences between basic automation and genuinely intelligent network operations.
WiFi NOW’s Take:
AI Ops are not making enterprise Wi‑Fi autonomous overnight. The practical transformation will happen one operational task at a time. The immediate opportunity is to reduce alarm noise, correlate symptoms, accelerate root-cause analysis, and give network teams better recommendations. The next stage is bounded automation for repetitive and well-understood problems. More extensive autonomy will depend on data quality, explainability, governance, and the ability to verify outcomes. The decisive measure of an AI Ops platform is therefore not how convincingly it talks about the network. It is whether it can identify the right problem, recommend the right action, and demonstrate that the action improved the user experience.